Free tool to read characters from photos and screenshots and convert them into text (OCR)
Learn about OCR (Optical Character Recognition) for extracting text from images. We explain how in-browser processing works, the need to fetch language data, and how image quality and language selection affect results.
§Trying Image-to-Text Transcription and Verifying Results with Sample Images
When extracting text from images to eliminate manual typing, in-browser optical character recognition (OCR) offers an accessible solution. This walkthrough demonstrates the end-to-end extraction workflow using real sample images, highlights key output behaviors, and guides you through reviewing and correcting results directly within the tool before saving.
Preparing Sample Assets
To evaluate how image dimensions influence recognition, we use two custom PNG files: a full-resolution Clear Image (1200x330) and a downscaled Reduced Image (360x99). The original source text (original.txt) consists of the following three lines:
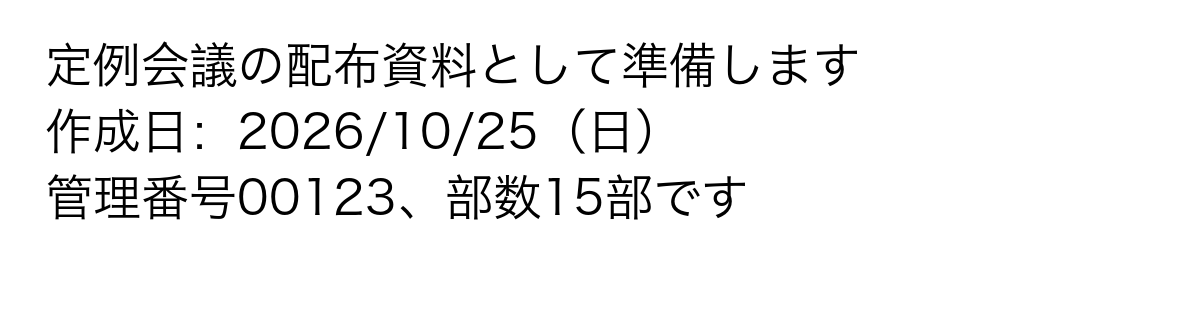
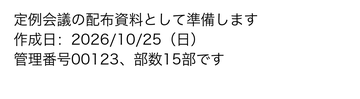
定例会議の配布資料として準備します
作成日:2026/10/25(日)
管理番号00123、部数15部です
Step-by-Step Instructions
1. Open the Offline OCR Tool and load a sample image (the clear or reduced image).
2. Specify Japanese as the recognition language using the Japanese button (loading a sample image automatically selects Japanese). Language data files are downloaded into your browser on initial use, but image processing runs locally on your device.
3. Click "Extract Text" to start recognition.
4. Compare the extracted text in the result area against the source image.
5. Because the result area is an editable textarea, review and manually correct any unwanted spaces or punctuation shifts.
6. After editing, click to copy the text or save it as a .txt file.
Reading the Results and Actual Output
Both the 1200x330 clear image and the 360x99 reduced image produced identical raw, unedited text output across all three lines:
定例 会 議 の 配布 資料 と し て 準備 し ます
作成 日 : 2026/10/25 (日 )
管理 番号 00123、 部 数 15 部 で す
You can inspect the exported raw output files directly: Clear Output and Reduced Output. In this test, the following specific behaviors were observed:
- Spacing Inconsistencies: Spurious whitespace is inserted between kanji and kana characters.
- Punctuation Shifts: Full-width punctuation altered to half-width equivalents, such as the colon
:shifting to:and parentheses(日)converting to(日 )with trailing whitespace. - Preserved Identifiers: The numeric identifier
00123retained its leading zeros.
Reviewing and Correcting Discrepancies
The textarea displaying the OCR result allows direct editing. Once text extraction is complete, compare the output side-by-side with your source image, delete unwanted spaces, and adjust shifted punctuation. After making corrections, you can copy the text or download the finalized content using the txt download button. If recognition quality is severely degraded, adjust image contrast, re-crop margins, or ensure the source image is level before retrying.
For additional workflow recommendations, see the Practical Guide.
Note (Testing Environment): Verified on 2026-10-25 using an in-app browser on macOS desktop. Physical mobile devices were not verified.
§1. Extracting text from images for business and learning
Manually transcribing text from images—such as PC screenshots, scanned documents, receipts, or photos of whiteboards—is a common yet time-consuming task. Whether you need to extract an error message to search for a solution, digitize printed materials for a research project, or copy complex reference codes, URLs, and serial numbers, typing out each character by hand significantly interrupts your workflow. Using an OCR (Optical Character Recognition) tool offers a more efficient approach, automatically converting the pixels in an image file into selectable and editable text data, saving you from tedious manual data entry.
However, while OCR is highly convenient, it is essential to understand that the automated extraction is not flawless. Users must be cautious of potential misreadings, particularly when dealing with similar-looking characters such as the number "0" and the uppercase letter "O", or the number "1" and the lowercase letter "l". Important details like financial figures, specific dates, or proper nouns always require a thorough manual review. Relying solely on the raw output without verification can lead to critical errors in your work, so always double-check the extracted text against your original image.
§2. Explanation of the cause: Why can't I copy and paste images? How OCR works and its limitations
Image files (such as JPEG, PNG, WebP, and GIF) are not recognized as characters by a computer; they are simply a collection of "color pixels" (colored dots). Therefore, it is not possible to select and copy the text range as you would in a regular document.
OCR (Optical Character Recognition) is a technology that analyzes this pixel arrangement, matches it with the shape of human characters, and reconstructs it into readable text data. While modern OCR engines are highly advanced, they are not infallible. The accuracy of the extracted text heavily depends on the quality of the source image. The following problems can significantly reduce recognition accuracy:
- Low image quality or out of focus: If the outline of the characters is blurry or ambiguous, the OCR engine will struggle to identify the correct letters, leading to incorrect transcription.
- Low contrast: If the border between the background color and the text color is too subtle (e.g., light gray text on a white background), the engine may fail to separate the text from the background, resulting in skipped words or complete failure to recognize the text.
- Image distortion and angle: If a photo is taken from a slanted angle, or if the paper is curved, the letters will appear distorted.
- Handwriting and rare characters: Complex layouts, cursive handwriting, and extremely rare characters or non-standard fonts are inherently difficult for OCR algorithms to process accurately.
To achieve the best results, it is essential to prepare your images properly. Since many tools do not include built-in cropping or rotation features, you should use your device's default photo editor to ensure the image is clear, well-lit, and straight before processing. Additionally, be aware that while some cloud-based OCR services are convenient, processing sensitive documents requires understanding how your data is handled, as uploading files to external servers introduces different data management considerations compared to client-side processing.
§3. Solve with tools: Using ZeroTools for browser-based text extraction
Our site's Image character recognition/offline OCR extraction tool provides a convenient way to extract text from your images directly in your browser. This tool utilizes the Tesseract.js library to perform OCR processing. While the image analysis happens within your browser's local memory, the tool may need to fetch the OCR engine core and necessary language data files from a Content Delivery Network (CDN) depending on cache status or when switching languages. If these required resources cannot be obtained due to network restrictions, the tool will be unable to process images. Please ensure your network allows these standard connections while maintaining your regular security protections. For more details on the resources required, refer to the Tesseract.js local installation documentation.
Additionally, note that this tool does not support direct PDF input; you must prepare your document pages as separate image files beforehand. Adhere to your organization's policies regarding highly confidential documents.
Solution steps and usage guide
1. Open the Image character recognition/offline OCR extraction tool in your web browser.
2. Select one image file (PNG, JPEG, WebP, GIF) or drag and drop it into the upload zone. If you drag and drop multiple files at once, only the first image will be loaded and processed. Batch processing is not supported.
3. Choose the appropriate language for the text in your image: either Japanese (default) or English. Selecting the language that matches your document is critical; choosing the wrong language will result in failed or highly inaccurate extraction.
4. Click the "Executing text extraction" button.
5. The progress bar will indicate the status of the operation. Please note that a progress of 100% simply means the processing operation has finished; it does not guarantee that the extracted text is 100% accurate.
6. Once completed, the extracted text will appear in the editable text area on the right.
7. Crucial Review Step: Always test a small sample first and compare the output line by line with your original image. OCR engines often misread critical details like names, digits, decimals, and dates.
8. You can edit the text directly within the text area to correct any mistakes before saving.
9. Click the copy icon to copy the corrected text to your clipboard, or click the download icon to save it as a standard UTF-8 text file on your device.
By preparing a clear, well-lit, and straight image externally before using the tool, and thoroughly reviewing the output, you can efficiently digitize text from images.
After checking the extracted text against the image, use the Word Counter to check its length before submitting or sharing it.